GitHub - bytedance/deer-flow: An open-source long-horizon SuperAgent harness that researches, codes, and creates. With the help of sandboxes
🦌 DeerFlow - 2.0 English | 中文 | 日本語 | Français | Русский On February 28th, 2026, DeerFlow claimed the 🏆 #1 spot on GitHub Trending following the launch of version 2. Thanks a million to our incredible community — you made this happen! 💪🔥 DeerFlow ( D eep
社区作者 · zZz
它解决什么问题
🦌 DeerFlow - 2.0
English | 中文 | 日本語 | Français | Русский
On February 28th, 2026, DeerFlow claimed the 🏆 #1 spot on GitHub Trending following the launch of version 2. Thanks a million to our incredible community — you made this happen! 💪🔥
DeerFlow ( D eep E xploration and E fficient R esearch Flow ) is an open-source super agent harness that orchestrates sub-agents , memory , and sandboxes to do almost anything — powered by extensible skills .
deer-flow-720p.mp4
Note DeerFlow 2.0 is a ground-up rewrite. It shares no code with v1. If you're looking for the original Deep Research framework, it's maintained on the 1.x branch — contributions there are still welcome. Active development has moved to 2.0.
Official Website
Learn more and see real demos on our official website . The landing-page case studies open as allowlisted, read-only showcases without requiring a sign-in.
Sister Projects
- LLM Space - Meet our secret weapon behind DeerFlow — one desktop tool to prototype agent ideas, inspect each harness step, replay failures, and benchmark performance.
Coding Plan from ByteDance Volcengine
- We strongly recommend using Doubao-Seed-2.0-Code, DeepSeek v3.2 and Kimi 2.5 to run DeerFlow
- Learn more
- 中国大陆地区的开发者请点击这里
InfoQuest
InfoQuest reader, web search, and image search use a 30-second HTTP connect/read inactivity timeout. The crawl timeout and navigation_timeout settings remain separate server-side options; they do not control the local HTTP timeout.
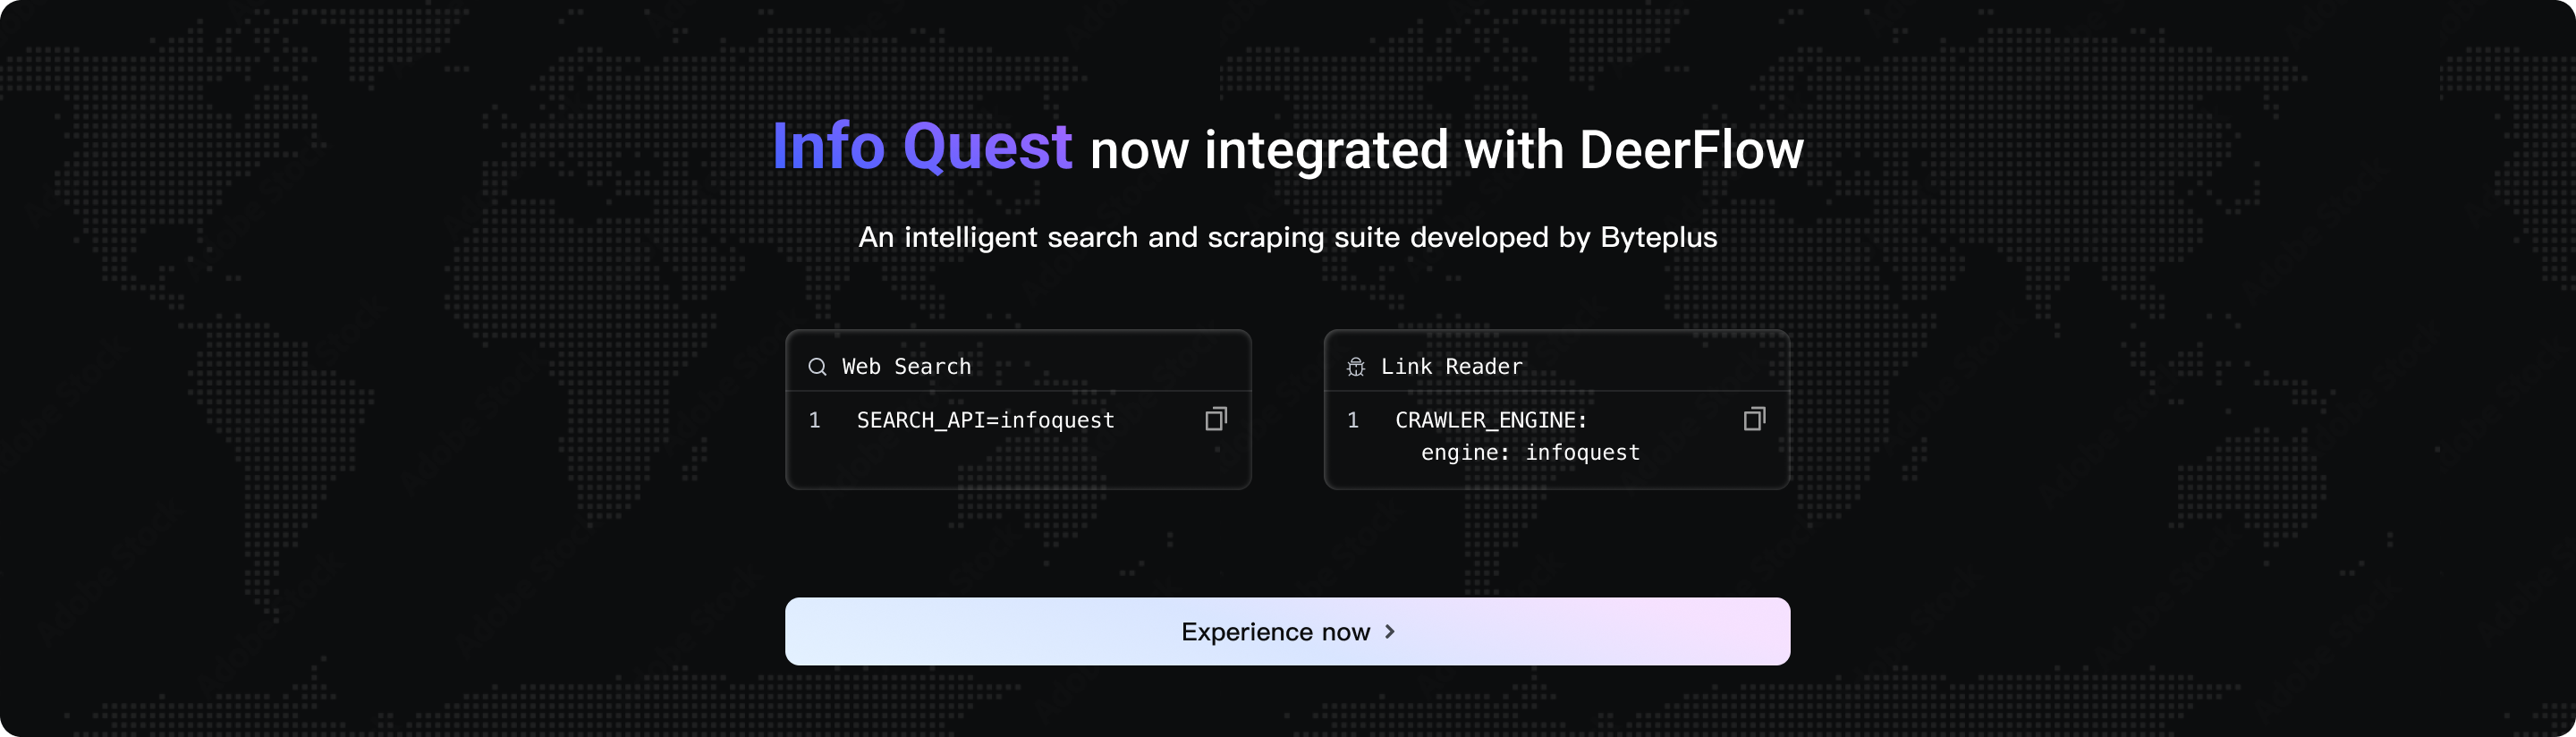
DeerFlow has newly integrated the intelligent search and crawling toolset independently developed by BytePlus-- InfoQuest (supports free online experience)
Table of Contents
- 🦌 DeerFlow - 2.0
- Official Website
- Coding Plan from ByteDance Volcengine
- InfoQuest
- Table of Contents
- One-Line Agent Setup
- Quick Start
- Configuration
- Running the Application
- Deployment Sizing
Option 1:
Docker (Recommended)- Option 2: Local Development
- Advanced
- Sandbox Mode
- MCP Server
- IM Channels
- LangSmith Tracing
- Langfuse Tracing
- Monocle Tracing
- Using Multiple Providers
- Personal Access Tokens
- From Deep Research to Super Agent Harness
- Core Features
- Skills & Tools
- Claude Code Integration
- Session Goals
- Manual Context Compaction
- Sub-Agents
- Sandbox & File System
- Context Engineering
- Long-Term Memory
- Recommended Models
- Embedded Python Client
- Scheduled Tasks
- Terminal Workbench (TUI)
- Documentation
- ⚠️ Security Notice
- Improper Deployment May Introduce Security Risks
- Security Recommendations
- Contributing
- License
- Acknowledgments
- Key Contributors
- Star History
One-Line Agent Setup
If you use Claude Code, Codex, Cursor, Windsurf, or another coding agent, you can hand it the setup instructions in one sentence:
Help me clone DeerFlow if needed, then bootstrap it for local development by following https://raw.githubusercontent.com/bytedance/deer-flow/main/Install.md
That prompt is intended for coding agents. It tells the agent to clone the repo if needed, choose Docker when available, and stop with the exact next command plus any missing config the user still needs to provide.
Quick Start
Configuration
- Clone the DeerFlow repository
git clone https://github.com/bytedance/deer-flow.gitcd deer-flow- Run the setup wizard
From the project root directory ( deer-flow/ ), run:
make setupThis launches an interactive wizard that guides you through choosing an LLM provider, optional web search, and execution/safety preferences such as sandbox mode, bash access, and file-write tools. It generates a minimal config.yaml and writes your keys to .
env . Takes about 2 minutes.
The wizard also lets you configure an optional web search provider, or skip it for now.
Run make doctor at any time to verify your setup and get actionable fix hints. If you are opening a GitHub issue about a local setup or runtime problem, run
make support-bundle . The command prints reporter next steps, writes a*-issue-summary.md file to paste into the issue, a *-issue-draft.md file for AI-assisted issue filing, and an optional evidence zip under .deer-flow/support-bundles/ .
If an AI assistant files the issue, start from the draft and replace every REQUIRED placeholder instead of inventing missing facts. Attach the zip only if a maintainer asks for it, or if the summary alone is not enough.
Maintainers and AI triage tools can start with triage.json ; the bundle includes redacted diagnostics and file manifests only, and does not include .env , raw conversation messages, or user file contents.
Advanced / manual configuration : If you prefer to edit config.yaml directly, run make config instead to copy the full template. See config.example.
yaml for the complete reference including CLI-backed providers (Codex CLI, Claude Code OAuth), OpenRouter, Responses API, subagent runtime caps such as subagents.max_total_per_run , and more.
Optional per-model pricing must use one currency across all priced models. DeerFlow disables Console cost estimates when currencies are mixed rather than presenting an invalid aggregate.
Manual model configuration examples models :
display_name : GPT-4o use : langchain_openai:ChatOpenAI model : gpt-4o api_key : $OPENAI_API_KEY
- name : gpt-4o
display_name : Gemini 2.5 Flash (OpenRouter) use : langchain_openai:ChatOpenAI model : google/gemini-2.5-flash-preview api_key : $OPENROUTER_API_KEY base_url : https://openrouter.ai/api/v1
- name : openrouter-gemini-2.5-flash
display_name : GPT-5 (Responses API) use : langchain_openai:ChatOpenAI model : gpt-5 api_key : $OPENAI_API_KEY use_responses_api : true output_version : responses/v1
- name : gpt-5-responses
display_name : Qwen3 32B (vLLM) use : deerflow.models.vllm_provider:VllmChatModel model : Qwen/Qwen3-32B api_key : $VLLM_API_KEY base_url : http://localhost:8000/v1 supports_thinking : true when_thinking_enabled : extra_body : chat_template_kwargs : enable_thinking : true
- name : qwen3-32b-vllm
OpenRouter and similar OpenAI-compatible gateways should be configured with langchain_openai:ChatOpenAI plus base_url . If you prefer a provider-specific environment variable name, point api_key at that variable explicitly (for example api_key: $OPENROUTER_API_KEY ).
To route OpenAI models through /v1/responses , keep using langchain_openai:ChatOpenAI and set use_responses_api: true with output_version: responses/v1 .
The setup wizard includes a Z.AI GLM-5.3-Flash profile.
Because that model requires thinking and only accepts its own restricted effort levels, the compatibility profile keeps thinking enabled for every foreground and background call and temporarily suppresses DeerFlow's generic effort selector. See config.
example.yaml for the equivalent manual configuration.
For vLLM 0.19.0, use deerflow.models.vllm_provider:VllmChatModel . For Qwen-style reasoning models, DeerFlow toggles reasoning with extra_body.chat_template_kwargs.
enable_thinking and preserves vLLM's non-standard reasoning field across multi-turn tool-call conversations. Legacy thinking configs are normalized automatically for backward compatibility.
If the endpoint reports a cumulative usage snapshot on every streaming chunk, set cumulative_stream_usage: true so DeerFlow converts those snapshots into per-chunk deltas; the option is disabled by default and leaves usage unchanged when a stable completion id is unavailable.
Reasoning models may also require the server to be started with --reasoning-parser . . If your local vLLM deployment accepts any non-empty API key, you can still set VLLM_API_KEY to a placeholder value.
CLI-backed provider examples:
models :
display_name : GPT-5.4 (Codex CLI) use : deerflow.models.openai_codex_provider:CodexChatModel model : gpt-5.4 supports_thinking : true supports_reasoning_effort : true
- name : gpt-5.4
display_name : Claude Sonnet 4.6 (Claude Code OAuth) use : deerflow.models.claude_provider:ClaudeChatModel model : claude-sonnet-4-6 max_tokens : 4096 supports_thinking : true
- name : claude-sonnet-4.6
- Codex CLI reads ~/.codex/auth.json
- Claude Code accepts CLAUDE_CODE_OAUTH_TOKEN , ANTHROPIC_AUTH_TOKEN , CLAUDE_CODE_CREDENTIALS_PATH , or ~/.claude/.credentials.json
- ACP agent entries are separate from model providers — if you configure acp_agents.codex , point it at a Codex ACP adapter such as npx -y @zed-industries/codex-acp
- MiniMax Code speaks ACP directly. Install and authenticate it, then add it as an ACP agent:
npm install --global @minimax-ai/codemcode login
acp_agents : mcode : command : mcode args : ["acp"] description : MiniMax Code for implementation, refactoring, debugging, and repository tasks auto_approve_permissions : false
mcode must be on the Gateway process's PATH ; installing it only on the Docker host does not make it available inside the Gateway container. DeerFlow invokes it through invoke_acp_agent in a per-thread ACP workspace and forwards enabled MCP servers.
Keep auto_approve_permissions: false for untrusted tasks; enable it only when MCode must edit files or run commands and you trust the task.
- On macOS, export Claude Code auth explicitly if needed:
eval " $( python3 scripts/export_claude_code_oauth.py --print-export ) "
API keys can also be set manually in .env (recommended) or exported in your shell:
OPENAI_API_KEY=your-openai-api-keyTAVILY_API_KEY=your-tavily-api-keyRunning the Application
Deployment Sizing
Use the table below as a practical starting point when choosing how to run DeerFlow:
Deployment target Starting point Recommended Notes
Local evaluation / make dev 4 vCPU, 8 GB RAM, 20 GB free SSD 8 vCPU, 16 GB RAM Good for one developer or one light session with hosted model APIs. 2 vCPU / 4 GB is usually not enough.
Docker development / make docker-start4 vCPU, 8 GB RAM, 25 GB free SSD 8 vCPU, 16 GB RAM Image builds, bind mounts, and sandbox containers need more headroom than pure local dev.
Long-running server / make up 8 vCPU, 16 GB RAM, 40 GB free SSD 16 vCPU, 32 GB RAM Preferred for shared use, multi-agent runs, report generation, or heavier sandbox workloads.
- These numbers cover DeerFlow itself. If you also host a local LLM, size that service separately.
- Linux plus Docker is the recommended deployment target for a persistent server. macOS and Windows are best treated as development or evaluation environments.
- If CPU or memory usage stays pinned, reduce concurrent runs first, then move to the next sizing tier.
Option 1
Docker (Recommended)Requires Docker Desktop / Docker Engine and Docker Compose v2.24+ ( docker compose version ). Older Compose clients cannot parse the optional env_file syntax in docker/docker-compose-dev.yaml .
Development (hot-reload, source mounts):
make docker-init # Pull sandbox image (only once or when image updates)make docker-start # Start services (auto-detects sandbox mode from config.yaml)make docker-logs # View logsmake docker-start starts provisioner only when config.yaml uses provisioner mode ( sandbox.use: deerflow.community.aio_sandbox:AioSandboxProvider with provisioner_url ).Docker builds use the upstream uv registry by default. If you need faster mirrors in restricted networks, export UV_INDEX_URL=https://pypi.tuna.tsinghua.edu.cn/simple and NPM_REGISTRY=https://registry.npmmirror.com before running make docker-init or make docker-start .Local AIO sandbox control traffic is always direct: loopback/private addresses, single-label cluster hosts, and Docker/Podman internal hostnames do not inherit HTTP_PROXY or HTTPS_PROXY . External sandbox FQDNs and public IPs still honor environment proxy settings.
Backend processes automatically pick up config.yaml changes on the next config access, so model metadata updates do not require a manual restart during development. The checkpoint storage settings database.checkpoint_channel_mode and database.checkpoint_delta.
snapshot_frequency (default 10 ) are exceptions: both are frozen when the process first builds an agent (including through DeerFlowClient ) and require a process restart to change safely.
The optional database.checkpoint_cache section (delta channel mode only) caches materialized checkpoint histories: type is memory (default) or redis , and max_entries: 0 disables the cache.
The redis backend is Gateway/async-only; the sync TUI/embedded path supports memory only.
The cache is performance-only — results are identical with it disabled — so it is never frozen and workers sharing one checkpoint database may safely run different cache settings.
Tip On Linux, if Docker-based commands fail with permission denied while trying to connect to the Docker daemon socket at unix:///var/run/docker.sock , add your user to the docker group and re-login before retrying. See CONTRIBUTING.md for the full fix.
Production (builds images locally, mounts runtime config and data):
make up # Build images and start all production servicesmake down # Stop and remove containersAccess: http://localhost:2026
make up waits for the Gateway /health endpoint before reporting success.If the Gateway does not become healthy within the startup window, deployment exits non-zero and prints the container status plus recent Gateway logs.
The production image starts from its already-built environment and never resolves or installs Python dependencies at container startup.
For persistent deployments, configure database.backend as sqlite or postgres . The selected backend is shared by the LangGraph checkpointer, LangGraph Store, and DeerFlow application data.
The deprecated checkpointer section, when present, overrides the first two for backward compatibility.
The unified nginx endpoint is same-origin by default and does not emit browser CORS headers.
If you run a split-origin or port-forwarded browser client, set GATEWAY_CORS_ORIGINS to comma-separated exact origins such as http://localhost:3000 ; the Gateway then applies the CORS allowlist and matching CSRF origin checks.
Browser login uses HttpOnly session cookies. The login page offers a "keep me signed in" option that extends the browser session when the request is HTTPS (including trusted X-Forwarded-Proto: https ) or localhost HTTP.
The localhost exception uses the direct request Host and ignores forwarded host headers. Public HTTP deployments, including many temporary sandbox URLs, fall back to session cookies by default.
DeerFlow never stores the password in browser storage; the UI may remember only the email address.
DeerFlow still uses Forwarded / X-Forwarded-* headers to recover the browser-facing scheme and origin behind a proxy. The bundled nginx sets X-Forwarded-Proto , but preserves an upstream HTTPS value and does not overwrite every forwarded header.
Configure the outer trusted proxy to replace or strip client-supplied forwarding headers before traffic reaches DeerFlow.
Important The Gateway still owns active run tasks in process, so production defaults to a single Gateway worker ( GATEWAY_WORKERS=1 ). Multi-worker deployments require Postgres, the Redis stream bridge ( stream_bridge.type: redis ), run_ownership.
heartbeat_enabled: true , and run_events.backend: db ; process-local memory/JSONL event stores cannot enforce singleton delivery receipts across workers. The bridge shares SSE delivery and bounded Last-Event-ID replay across workers.
When a valid reconnect cursor has been trimmed, or a subscriber that already established an empty-stream wait falls behind before its first delivery, Memory and Redis emit a machine-readable SSE gap event instead of silently returning a partial replay; the Web UI reloads durable thread/event state and resumes from the retained tail.
Lease reconciliation marks runs from dead workers as errors, persists their delivery receipts, publishes the terminal stream marker, schedules retained-stream cleanup, and updates the affected thread status.
SSE, /wait , and internal stream consumers use stream_bridge.heartbeat_interval_seconds (default 15 ) for idle liveness checks; changing it requires a Gateway restart.
Malformed Redis reconnect IDs live-tail new events instead of replaying the retained buffer, and the rolling retained-buffer TTL ( stream_ttl_seconds ) remains a cleanup safety net rather than a run timeout.
IM channel state and other process-local services still need their own multi-worker coordination.
After a run publishes its terminal stream marker, its process-local RunRecord remains available for the existing five-minute grace period before cleanup; durable run history remains available through RunStore , while the stream bridge retains its delivery tail on its separate cleanup schedule.
Run cancellation may land on any Gateway worker.
A non-owning worker now persists the interrupt or rollback request for the live owner, which observes it during lease renewal and performs the normal cancellation flow; load-balancer routing alone no longer produces a 409.
The first accepted action wins even if a retry lands on the owner, and accepted cancellation competes atomically with owner completion. Dead owners still follow lease takeover and orphan recovery.
Cancellation latency is therefore bounded by the lease heartbeat interval.
Cancelling a model recovery probe, including while it is queued or waiting to retry, lets the next call check whether the provider has recovered. Cancellation does not count as a provider failure or release another call's active recovery probe.
With lease heartbeat enabled, a transient RunStore renewal error is retried only until the last confirmed lease expires; the stale worker then cancels local execution and suppresses checkpoint, completion-hook, delivery-receipt, and thread-status finalization.
A remote tool side effect already in flight may still be outside local cancellation.
Reconciliation uses an atomic takeover claim that re-checks the lease after candidate selection, so a successful owner renewal wins over orphan recovery and only one reconciler can report a run as recovered.
When multiple Gateway workers share the Docker/AIO or E2B sandbox backend, also configure sandbox.ownership.
type: redis ; E2B uses the leases during background startup and periodic reconciliation so duplicate/orphan cleanup cannot terminate a live peer's sandbox.
See CONTRIBUTING.md for detailed Docker development guide.
Option 2: Local Development
If you prefer running services locally:
Prerequisite: complete the "Configuration" steps above first ( make setup ). make dev requires a valid config.yaml in the project root. Set DEER_FLOW_PROJECT_ROOT to define that root explicitly, or DEER_FLOW_CONFIG_PATH to point at a specific config file.
Runtime state defaults to .deer-flow under the project root and can be moved with DEER_FLOW_HOME ; skills default to skills/ under the project root and can be moved with DEER_FLOW_SKILLS_PATH . Run make doctor to verify your setup before starting.
On Windows, run the local development flow from Git Bash. Native cmd.exe and PowerShell shells are not supported for the bash-based service scripts, and WSL is not guaranteed because some scripts rely on Git for Windows utilities such as cygpath .
The documented root make commands invoke repository .sh files through Bash explicitly. They therefore continue to work from source archives or filesystems that do not preserve POSIX executable bits.
When calling a script directly from such a checkout, use bash ./scripts/<name>.sh . .
- Check prerequisites :
make check # Verifies Node.js 22+, pnpm, uv, nginxThe local make check , make install , make dev , and make start entry points use a direct pnpm / pnpm.cmd executable when available and otherwise fall back to corepack pnpm .
The shared runner and diagnostics resolve repository paths absolutely, so these checks work regardless of the caller's current directory. Corepack runs from frontend/ , so it honors the packageManager version pinned in frontend/package.
json ; enabling a global pnpm shim is not required.
- Install dependencies :
make install # Install backend + frontend dependencies + pre-commit hooks- (Optional) Pre-pull sandbox image :
Recommended if using Docker/Container-based sandbox
make setup-sandbox- (Optional) Load sample memory data for local review :
python scripts/load_memory_sample.pyThis copies the sample fixture into the default local runtime memory file so reviewers can immediately test Settings > Memory . See backend/docs/MEMORY_SETTINGS_REVIEW.md for the shortest review flow.
- Start services :
make dev- Access : http://localhost:2026
Local services always use their internal ports ( 8001 , 3000 , and 2026 ). The root .env variable PORT configures only the published Docker ingress; it does not change the Next.js port used by make dev .
Startup Modes
DeerFlow runs the agent runtime inside the Gateway API. Development mode enables hot-reload; production mode uses a pre-built frontend.
Local Foreground Local Daemon
Docker DevDocker ProdDev
./scripts/serve.sh --devmake dev./scripts/serve.sh --dev --daemonmake dev-daemon./scripts/docker.sh startmake docker-start—
Prod
./scripts/serve.sh --prodmake start./scripts/serve.sh --prod --daemonmake start-daemon—
./scripts/deploy.shmake upAction Local
Docker DevDocker ProdStop
./scripts/serve.sh --stopmake stop./scripts/docker.sh stopmake docker-stop./scripts/deploy.sh downmake downRestart
./scripts/serve.sh --restart [flags]./scripts/docker.sh restart—
make start and make start-daemon rebuild the frontend with next build onevery run. To reuse the last build instead, pass SKIP_FRONTEND_BUILD=1 (or add --skip-frontend-build when calling ./scripts/serve.sh --prod directly). This is opt-in: it fails fast when frontend/.next has no completed build.
Gateway owns /api/langgraph/* and translates those public LangGraph-compatible paths to its native /api/* routers behind nginx.
For a read-only demo without the Gateway, run make build-static from frontend/ , then HOSTNAME=127.0.0.1 PORT=3000 node --env-file=.env .next/standalone/server.js from the same directory.
The build includes public demo assets and resolves supported demo API reads locally; writes are unavailable. To display the homepage GitHub star count, set GITHUB_OAUTH_TOKEN in frontend/.env before starting Node.
The token stays on the server; missing credentials or GitHub failures hide the count. Restart Node after changing the token; no rebuild is needed.
LangGraph Studio (Optional)
The default make dev topology uses DeerFlow's Gateway-embedded runtime and does not require LangGraph Studio. To inspect and test the registered lead-agent graph with the standalone development server, run the command from backend/ so the CLI discovers langgraph.json :
cd backenduv run langgraph dev --allow-blockingThe command prints the local API and Studio UI URLs. This in-memory server is for development and testing only.
The flag permits DeerFlow's synchronous configuration and graph-factory setup during local Studio requests; it must not be treated as a production-server setting.
Local Studio authentication is handled automatically, so the connection does not require custom headers. Use DeerFlow's documented production startup modes or a supported LangSmith deployment for production workloads.
Assistant ownership and provenance in this standalone mode are server-owned: Studio can discover registered graphs and the assistants it creates, and normal assistant-version selection remains available.
Before the locked local runtime loads its persisted development store, DeerFlow repairs legacy assistant rows and version history so historical client metadata cannot restore server privileges or be discarded by the runtime's startup cleanup.
Keep the backend dependencies synchronized with uv sync ; this compatibility path requires the declared LangGraph runtime versions and logs a warning if the persisted-store contract no longer matches its expectations.
The documented command uses LangGraph's file-based custom-app loader, which is also covered directly by DeerFlow's regression tests.
For workflows that invoke backend/langgraph.
json through LangGraph Studio or a direct LangGraph Server, DeerFlow consumes the authenticated identity published by that runtime and uses it for custom-agent configuration/SOUL, user skills and skill policy, uploads, thread data, and memory reads/writes.
This keeps authenticated runs out of the shared default filesystem bucket, and the server-owned identity takes precedence over ordinary client-supplied user_id values.
External identities such as email addresses are mapped to stable, collision-resistant directory-safe user IDs before accessing DeerFlow storage. The default DeerFlow service topology remains the Gateway-embedded runtime described above.
Gateway runs automatically enforce native delivery for artifacts created or modified under /mnt/user-data/outputs : present_files must present at least one output produced by the current run, and the terminal run.delivery receipt must be durably recorded.
Virtual artifact paths are resolved within the same authenticated user and thread scope that produced the output before the output-directory boundary is validated. Runs that do not produce output artifacts keep ordinary conversational behavior.
DeerFlow's built-in custom events are available through both LangGraph streaming interfaces: native clients can continue subscribing to stream_mode="custom" , while callback-based integrations can consume the same payloads as on_custom_event records from astream_events(version="v2") .
The callback event name matches the payload's type field.
Docker Production Deploymentdeploy.sh supports building and starting separately:
One-step (build + start)
deploy.sh
Two-step (build once, start later)
deploy.sh build # build all images deploy.sh start # start pre-built images
Stop
deploy.sh down
Advanced
Sandbox Mode
DeerFlow supports multiple sandbox execution modes:
- Local Execution (runs sandbox code directly on the host machine)
Docker Execution (runs sandbox code in isolated Docker containers)Docker Execution with Kubernetes (runs sandbox code in Kubernetes pods via provisioner service)When host Bash is enabled for Local Execution, DeerFlow starts OS detection with uname -s , then uses sw_vers on Darwin. On Linux, it reads host system files such as /etc/os-release only when the active sandbox policy permits it.
Host filesystem path checks still apply; after a blocked path, the agent is directed to use a permitted command-only probe or virtual path instead of repeating the rejected command.
For Docker development, service startup follows config.yaml sandbox mode. In Local/Docker modes, provisioner is not started.
See the Sandbox Configuration Guide to configure your preferred mode.
MCP Server
DeerFlow supports configurable MCP servers and skills to extend its capabilities. For HTTP/SSE MCP servers, OAuth token flows are supported ( client_credentials , refresh_token ).
For stdio MCP servers, per-tool call timeouts can be configured with tool_call_timeout ; durable background-task calls honor the same setting for HTTP/SSE servers as well.
MCP tool names are prefixed with <server_name>_ by default to prevent collisions across servers. If a server already namespaces its own tools, set tool_name_prefix: false on that server in extensions_config.json to keep the original names.
Disable the prefix only when the resulting names remain unique across all enabled servers.
Settings > Tools adds, replaces, and deletes one MCP server at a time through targeted mutations that preserve concurrent sibling changes; deletes use a bodyless URL-addressed request.
An invalid stdio command on one server no longer blocks toggling another, while enabling that invalid server remains protected by the command allowlist and surfaces the backend validation message in the UI.
Targeted updates accept both DeerFlow's type field and the MCP-spec transport field for SSE/
— 本文由 AI 根据公开来源辅助整理,命令、版本与许可证请在使用前到原始页面复核。
安装 / 开始使用
- Quick Start
- Configuration
- Running the Application
- Deployment Sizing
Option 1:
Docker (Recommended)One-Line Agent Setup If you use Claude Code, Codex, Cursor, Windsurf, or another coding agent, you can hand it the setup instructions in one sentence: Help me clone DeerFlow if needed, then bootstrap it for local development by following https://raw.
githubusercontent.com/bytedance/deer-flow/main/Install.md That prompt is intended for coding agents.
It tells the agent to clone the repo if needed, choose Docker when available, and stop with the exact next command plus any missing config the user still needs to provide. Quick Start Configuration - Clone the DeerFlow repository
- Option 2: Local Development
- Advanced
- Sandbox Mode
- MCP Server
- IM Channels
- LangSmith Tracing
- Langfuse Tracing
- Monocle Tracing
- Using Multiple Providers
- Personal Access Tokens
- From Deep Research to Super Agent Harness
- Core Features
- Skills & Tools
- Claude Code Integration
- Session Goals
- Manual Context Compaction
- Sub-Agents
- Sandbox & File System
- Context Engineering
- Long-Term Memory
- Recommended Models
- Embedded Python Client
- Scheduled Tasks
- Terminal Workbench (TUI)
- Documentation
- ⚠️ Security Notice
- Improper Deployment May Introduce Security Risks
- Security Recommendations
- Contributing
- License
- Acknowledgments
- Key Contributors
- Star History
git clone https://github.com/bytedance/deer-flow.gitcd deer-flow- Run the setup wizard From the project root directory ( deer-flow/ ), run:
make setupThis launches an interactive wizard that guides you through choosing an LLM provider, optional web search, and execution/safety preferences such as sandbox mode, bash access, and file-write tools. It generates a minimal config.yaml and writes your keys to .
env . Takes about 2 minutes. The wizard also lets you configure an optional web search provider, or skip it for now. Run make doctor at any time to verify your setup and get actionable fix hints.
If you are opening a GitHub issue about a local setup or runtime problem, run
make support-bundle . The command prints reporter next steps, writes a*-issue-summary.md file to paste into the issue, a *-issue-draft.md file for AI-assisted issue filing, and an optional evidence zip under .deer-flow/support-bundles/ .
If an AI assistant files the issue, start from the draft and replace every REQUIRED placeholder instead of inventing missing facts. Attach the zip only if a maintainer asks for it, or if the summary alone is not enough.
Maintainers and AI triage tools can start with triage.json ; the bundle includes redacted diagnostics and file manifests only, and does not include .env , raw conversation messages, or user file contents.
Advanced / manual configuration : If you prefer to edit config.yaml directly, run make config instead to copy the full template. See config.example.
yaml for the complete reference including CLI-backed providers (Codex CLI, Claude Code OAuth), OpenRouter, Responses API, subagent runtime caps such as subagents.max_total_per_run , and more.
Optional per-model pricing must use one currency across all priced models. DeerFlow disables Console cost estimates when currencies are mixed rather than presenting an invalid aggregate. Manual model configuration examples models :
display_name : GPT-4o use : langchain_openai:ChatOpenAI model : gpt-4o api_key : $OPENAI_API_KEY
display_name : Gemini 2.5 Flash (OpenRouter) use : langchain_openai:ChatOpenAI model : google/gemini-2.5-flash-preview api_key : $OPENROUTER_API_KEY base_url : https://openrouter.ai/api/v1
display_name : GPT-5 (Responses API) use : langchain_openai:ChatOpenAI model : gpt-5 api_key : $OPENAI_API_KEY use_responses_api : true output_version : responses/v1
- name : gpt-4o
- name : openrouter-gemini-2.5-flash
- name : gpt-5-responses